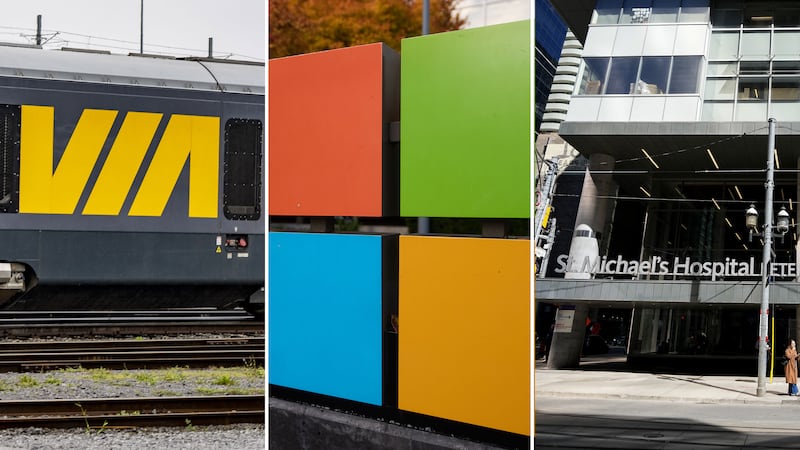
A Toronto hospital network has declared a “Code Grey” amid the Microsoft outage that’s been affecting users worldwide. In a statement, Unity Health Toronto, which includes St. Michael’s Hospital, said its staff is experiencing difficulties sending and receiving emails. According to the hospital network, a Code Grey is called when there is a loss or failure of infrastructure. Unity Health Toronto advised anyone who needs to reach a clinic or department about an upcoming appointment to call the main hospital line if urgent. “Please be advised that patient and resident care is not affected by the outage. Our hospitals remain safe and open to provide care,” Unity Health said. “We will continue to monitor the situation while Microsoft works to restore services.” Other health networks also impacted The University Health Network said its email services are temporarily unavailable. “There is no impact on patient care delivery,” UHN said in a notice on its website. Sunnybrook Hospital is also urging patients with urgent appointments to call the main telephone line, as staff is not able to send or receive emails. The hospital noted that it remains safe and open to provide care. Several post-secondary institutions say their email services are impacted by the Microsoft outage. They include the University of Toronto, Seneca Polytechnic, and George Brown Polytechnic. It doesn’t appear classes are affected by the outage. VIA Rail said passengers may not be able to receive email communications about their trip due to the outage. Microsoft first reported that it was investigating the issue at around 1 p.m. Thursday. It has been constantly posting on social media updates on the work it’s doing to restore service. “We’re opening all available pathways to restore service, as our actions taken thus far have not provided the anticipated relief. We found a core process on affected servers is becoming overwhelmed, causing capacity loss,” Microsoft said in an update at 5:09 p.m. ET. “To validate a potential recovery, we’re isolating a portion of infrastructure, restarting affected components, and reintroducing traffic to confirm the services remain stable before applying the change more broadly.”